
Catch known regressions in coding-agent instructions before merging.



AgentConfigScore runs local, deterministic checks on AGENTS.md, CLAUDE.md,
Cursor, Copilot and Gemini instructions. It compares a change with its baseline,
reports rule-defined regressions, and uses reviewed baseline policies for CI
decisions. No model API or runtime dependencies are needed.
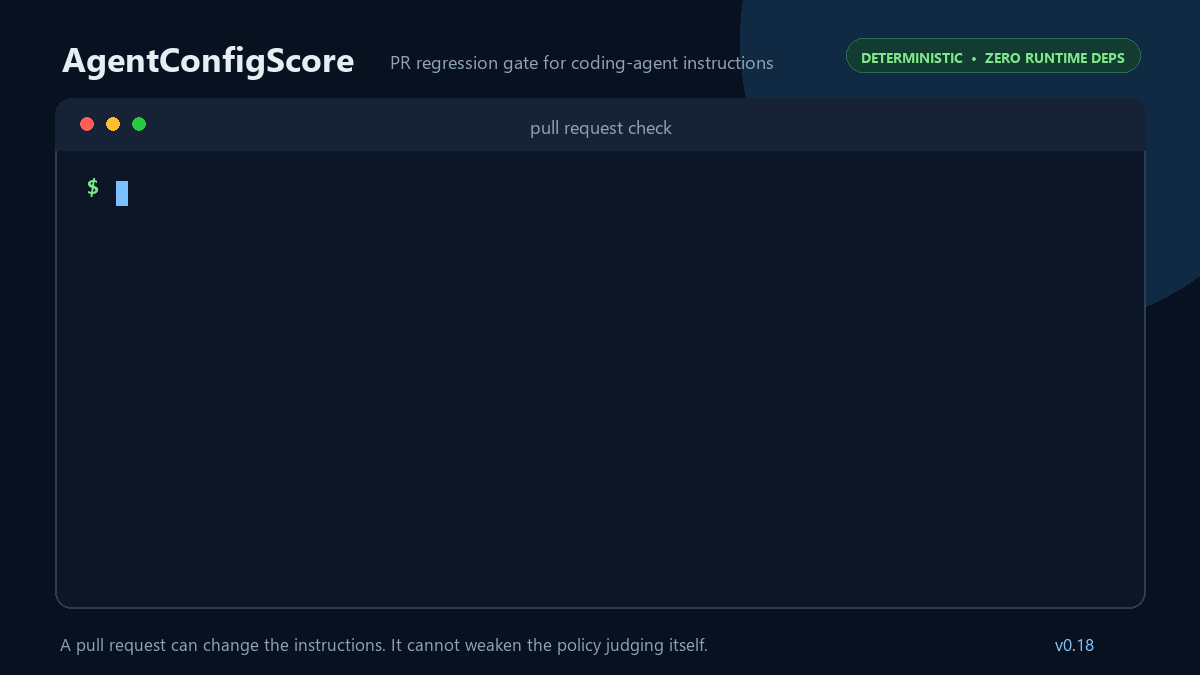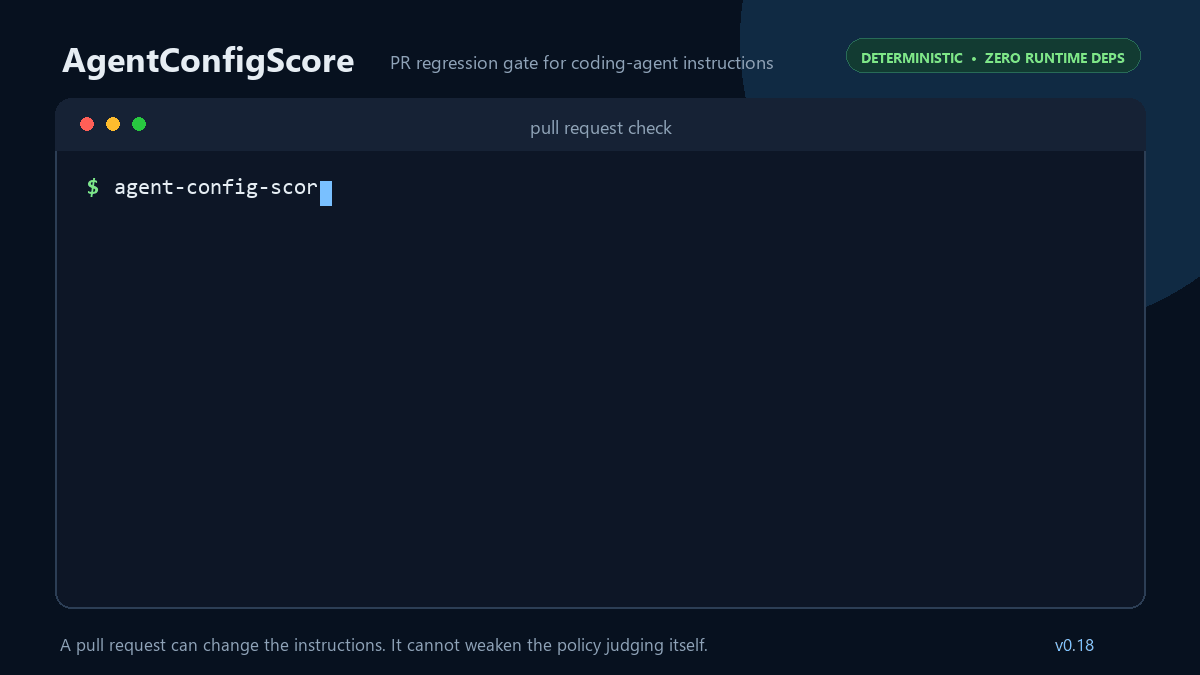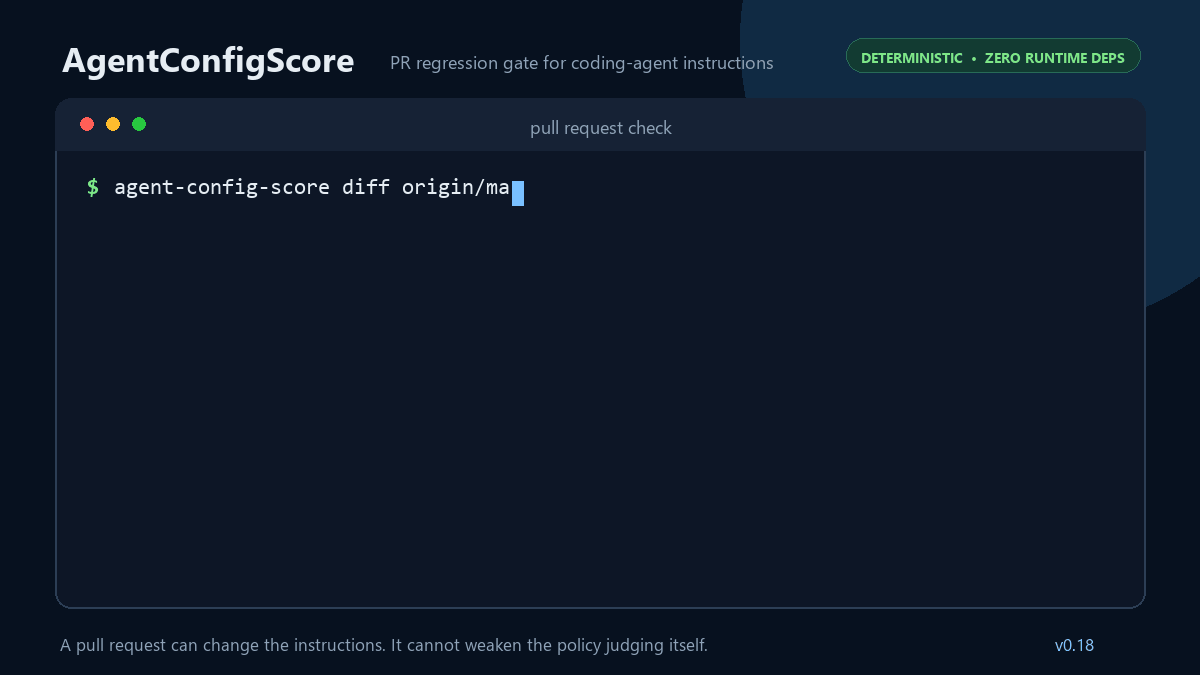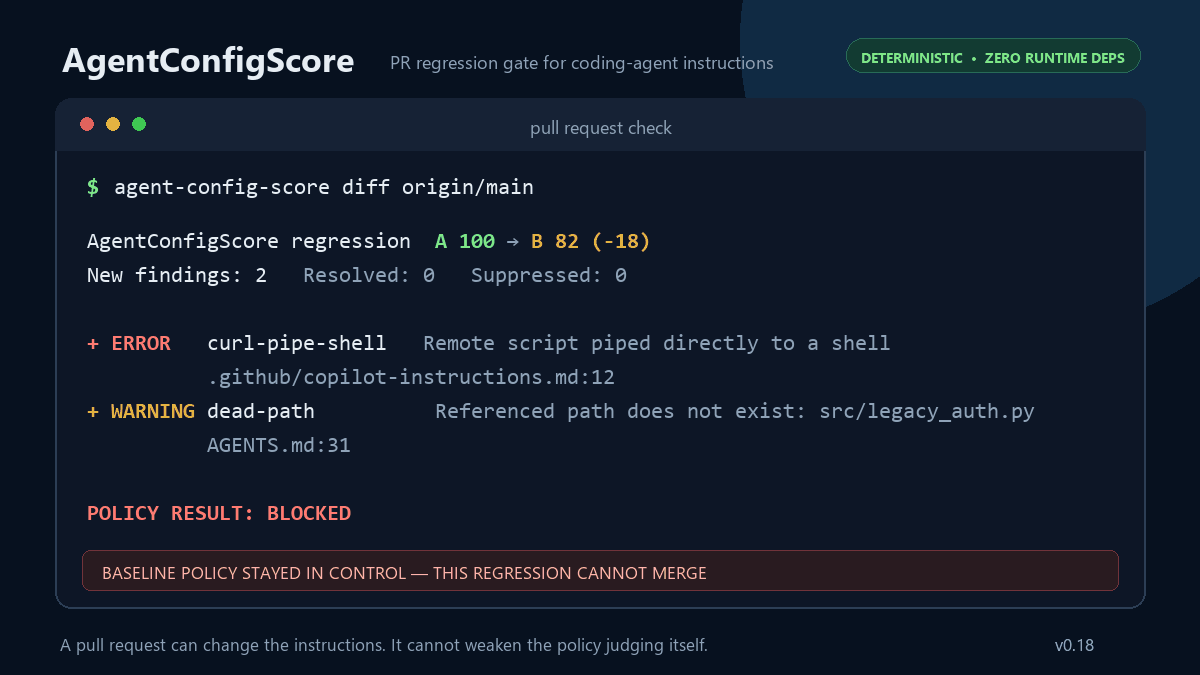
A 100 means no active deterministic rule matched. It does not certify instruction usefulness, semantic correctness or safety. Read the score contract and limitations.
| Change | Review evidence |
|---|---|
| Add a recognized unsafe command, exposed credential or broken path | Rule ID, explanation and source location where available |
| Delete an instruction file or reverse an exact directive | A regression-only finding, even when both numeric scores stay the same |
| Lower the candidate's threshold or add its own exception | The normal comparison still uses baseline policy and suppressions; trusted caller overrides are explicit |
| Accept a known exception | A reason, expiry and visible audit record |
Existing repositories can adopt the gate without first reaching 100.
init enables new-error blocking and no score decrease; a passing comparison
means no regression under the selected rules and policy.
Run inside your repository with a supported instruction file:
python -m pip install --upgrade agent-config-score
agent-config-score --version
agent-config-score init
agent-config-score doctor
agent-config-score diff
Review and commit the generated .agentconfigscore.json and
.github/workflows/agent-config-score.yml. init does not write your agent
instructions or overwrite conflicting setup files by default. acs and
python -m agent_config_score are alternative entrypoints.
diff includes uncommitted changes. It detects a conservative local baseline
without fetching; use agent-config-score diff origin/main when you want an
explicit ref. The user guide
covers setup, exits and troubleshooting.
| Version | Available capability |
|---|---|
| Published v0.24.0 | Local lint, baseline-governed regression gates, auditable exceptions, reports and opt-in deletion-safeguard review |
Unreleased source on main |
Cursor file-context activation and before/after attachment review, plus the fixes listed in the changelog |
The PyPI package and rolling v0 Action do not contain the unreleased
Cursor commands. See v0.24.0 release notes
and the changelog
before choosing an installation or Action revision.
An instruction can stop attaching even when its words and score stay unchanged. For a declared API-only task:
| Property | Baseline | Candidate |
|---|---|---|
| Instruction | Never delete files without approval. | Same text |
| Cursor glob | src/** |
src/web/** |
| Declared task file | src/api/service.py |
Same path |
| Ordinary scan score | 100 | 100 |
| Predicted automatic attachment | Active | Inactive |
From a source checkout, run the synthetic example:
python -m pip install -e .
agent-config-score scope compare \
  examples/cursor-scope-impact/base examples/cursor-scope-impact/narrowed \
  --target src/api/service.py --fail-on-lost-directives --fail-on-unknown
Expected exit 1: review is requested for the lost recognized active directive. Reports identify metadata and directive source lines. Another active copy or a remaining multi-file trigger can retain availability; manual/model-selected loading and unsupported inputs remain unknown.
The comparison models the same declared file context on both sides. It does not observe an agent run or prove semantic equivalence. Comparisons are advisory unless flags opt into the review gate; these flags are caller-owned and do not extend the existing baseline score-policy schema.
Try the four controls,
or use scope diff with a local Git baseline.
The generated policy enables regression checks:
{
  "$schema": "https://raw.githubusercontent.com/LE0-Lin/AgentConfigScore/v0/schema/agentconfigscore.schema.json",
  "version": 1,
  "policy": {
    "max_drop": 0,
    "fail_on_new_errors": true
  }
}
Normal diff / compare and the reusable Action use the baseline's policy,
so candidate threshold edits cannot approve that same change. The candidate
config is still validated. Explicit CLI/Action overrides belong to the trusted
caller. Policy defaults, schema and overrides.
An accepted exception requires a stable rule ID, reason and expiry. Suppressed findings remain visible. Normal regression comparisons apply the baseline suppression set to both sides; a PR cannot authorize its own new exception. Suppression format and audit behavior.
Discovery includes root/nested AGENTS.md and AGENTS.override.md,
CLAUDE.md, GEMINI.md, legacy .cursorrules, .cursor/rules/*.md / *.mdc,
.github/copilot-instructions.md, .github/instructions/*.md, .claude/**/*.md,
.clinerules and .windsurfrules. .agentconfigscoreignore excludes discovery paths.
Format discovery does not imply complete language or native loading semantics.
The dedicated Cursor profile models root .cursor/rules/ separately and treats
plain .md as ignored there. See scope/override handling
and copy-ready templates.
- Maintained synthetic contracts and negative controls check defined behavior. Known semantic misses remain visible; these are not real-world accuracy estimates.
- The current pinned-repository smoke corpus has five completed scans and one expected source rejection. Pinned Reaparr is rejected for a dangling instruction link and receives no score. Its historical A 100 predates strict source validation and is not the current result.
- An independent comparison with direct AI review has not been completed. See the comparison protocol. Scanning public repositories does not establish adoption.
A high score can miss vague guidance, paraphrased contradictions or harmful text outside the rule grammar. Local analysis does not call a model API or execute instruction-file commands. Reports can contain repository details; review them before sharing. Limits and privacy-minimized feedback drafts.
| Task | Reference |
|---|---|
| Install, initialize, understand exits | User guide |
| Configure policy, CLI, Action inputs/outputs or SARIF | Detailed reference |
| Explain findings or set up optional PR comments | Maintainer workflow |
| Review missing deletion safeguards | Opt-in guardrail suggestions |
| Inspect installed rules | agent-config-score rules |
| Keep score history | History workflow |
| Browse all topics | Documentation index |
Setup, workflow and history demos
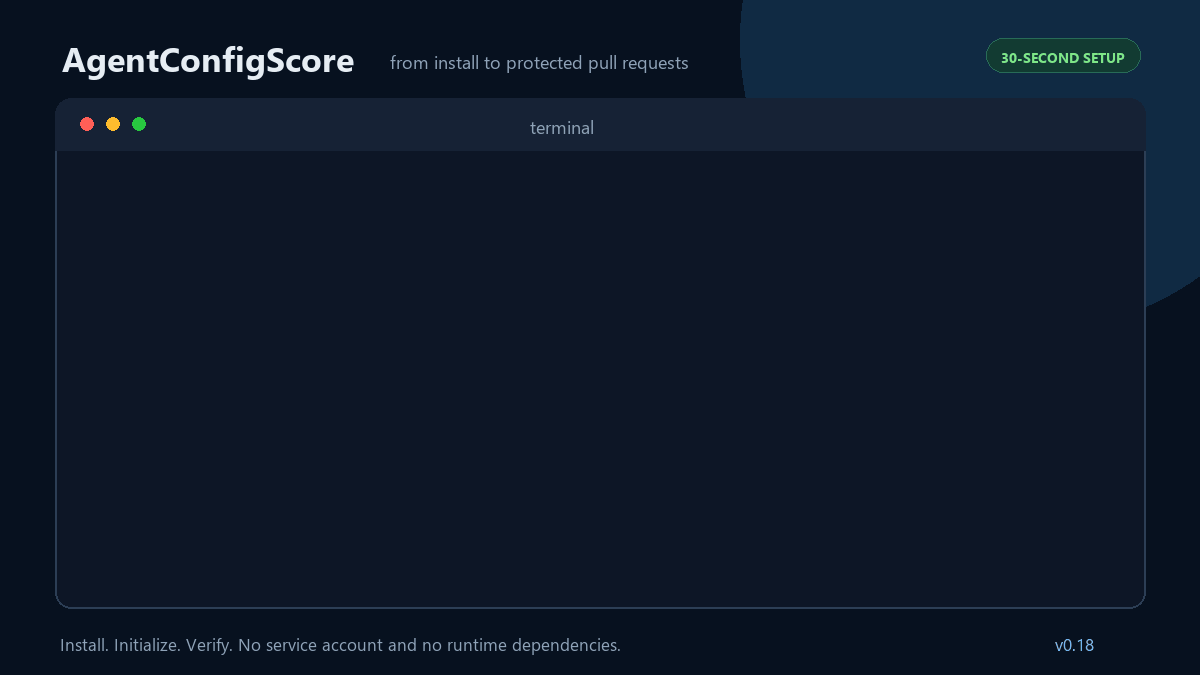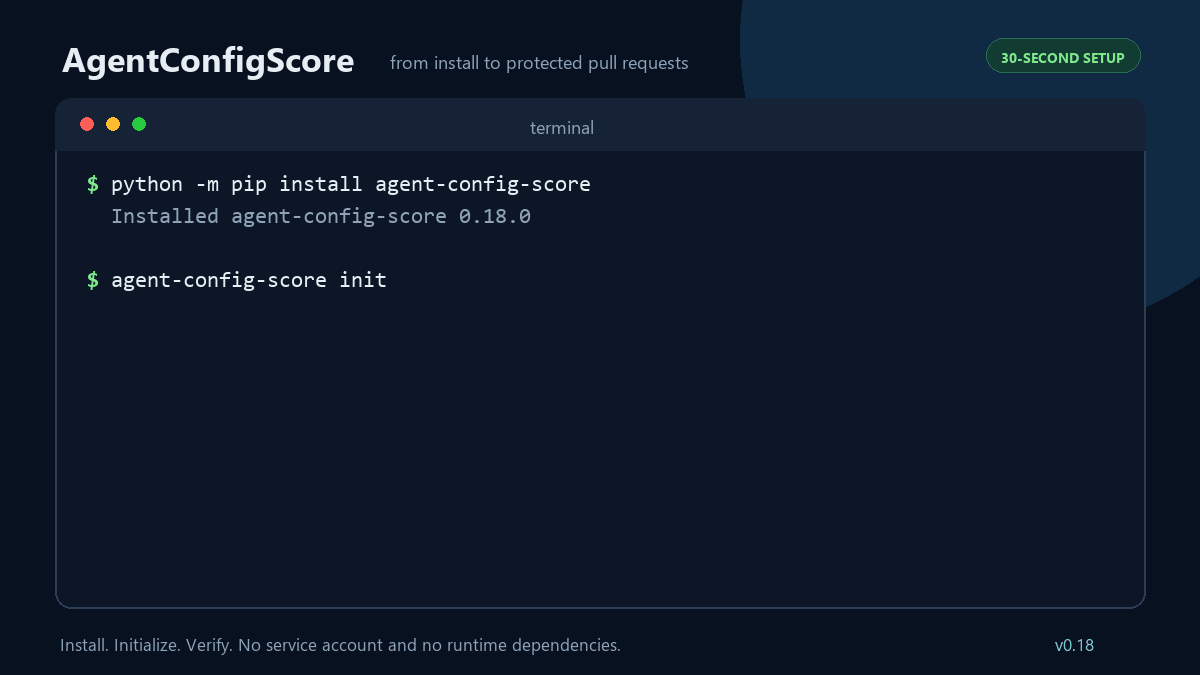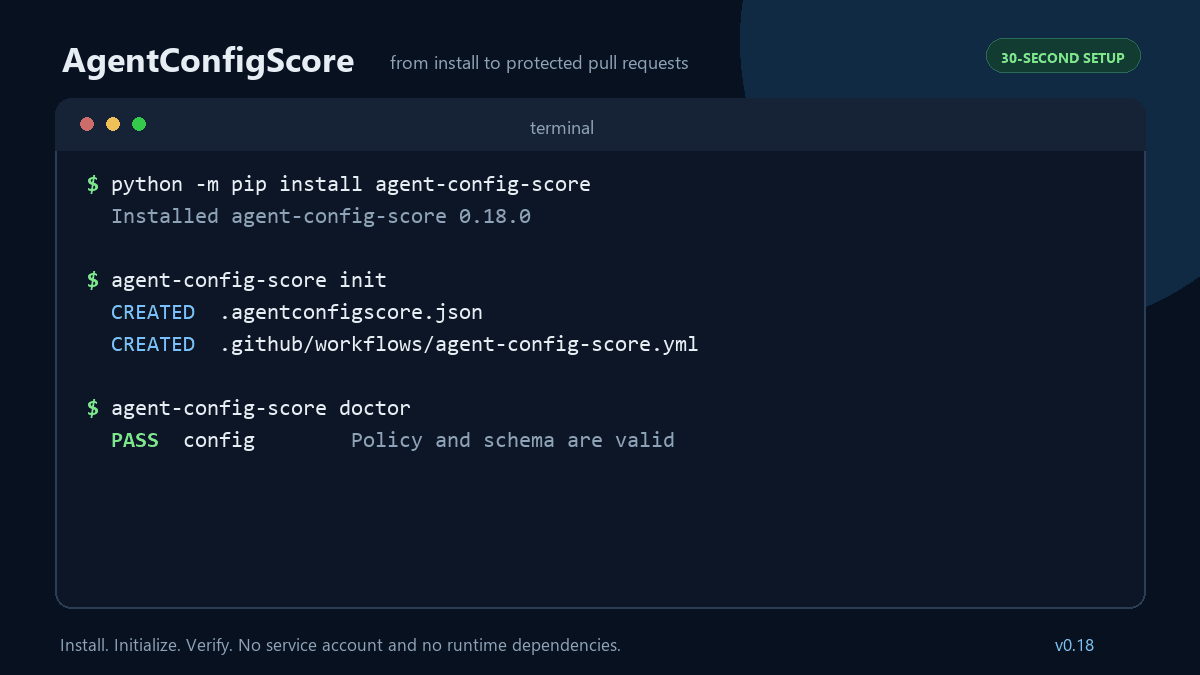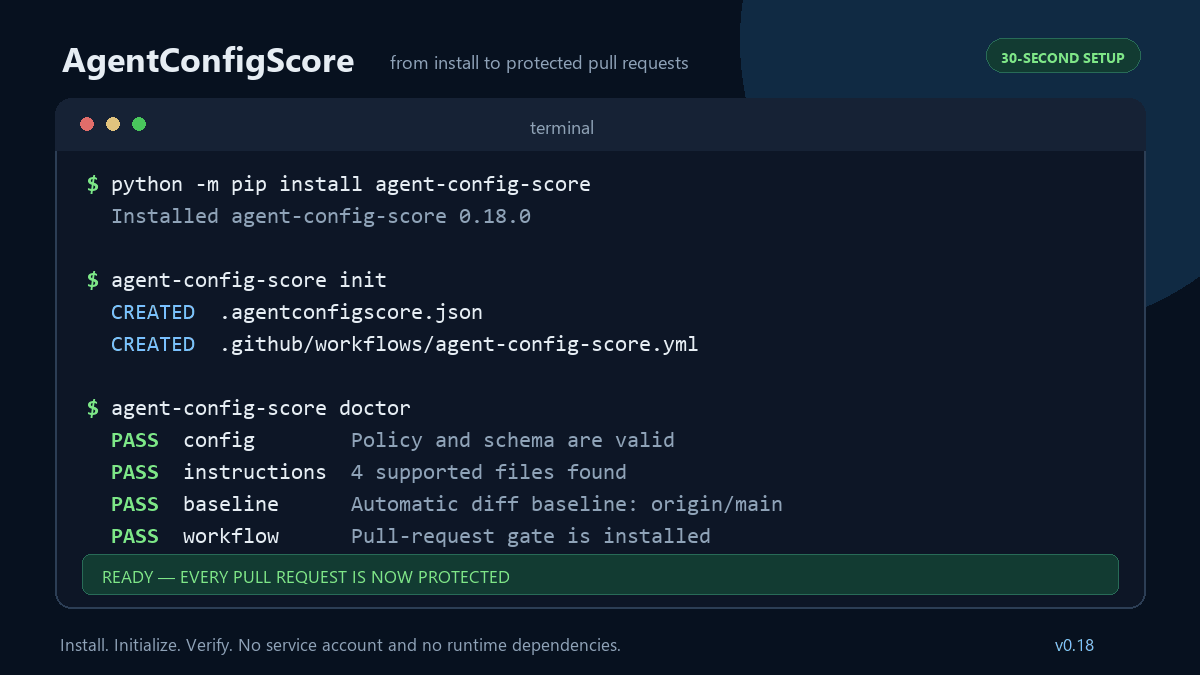
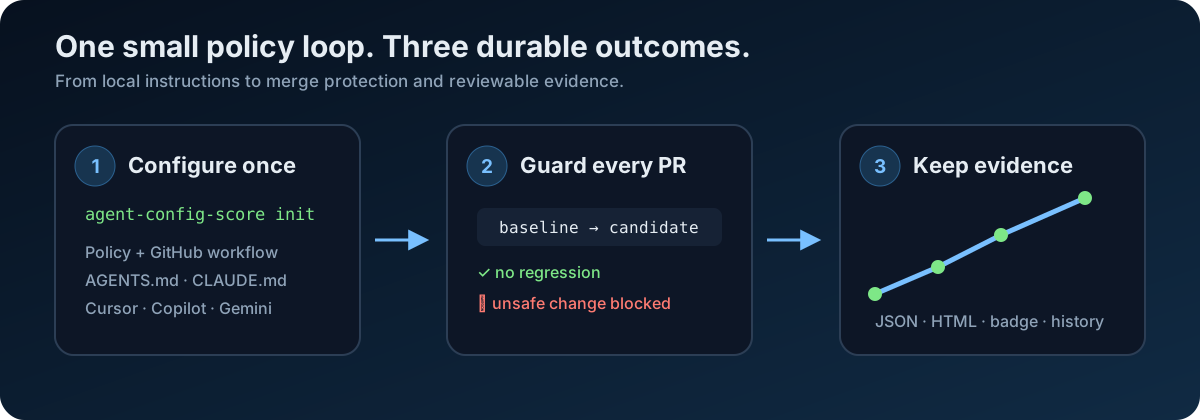
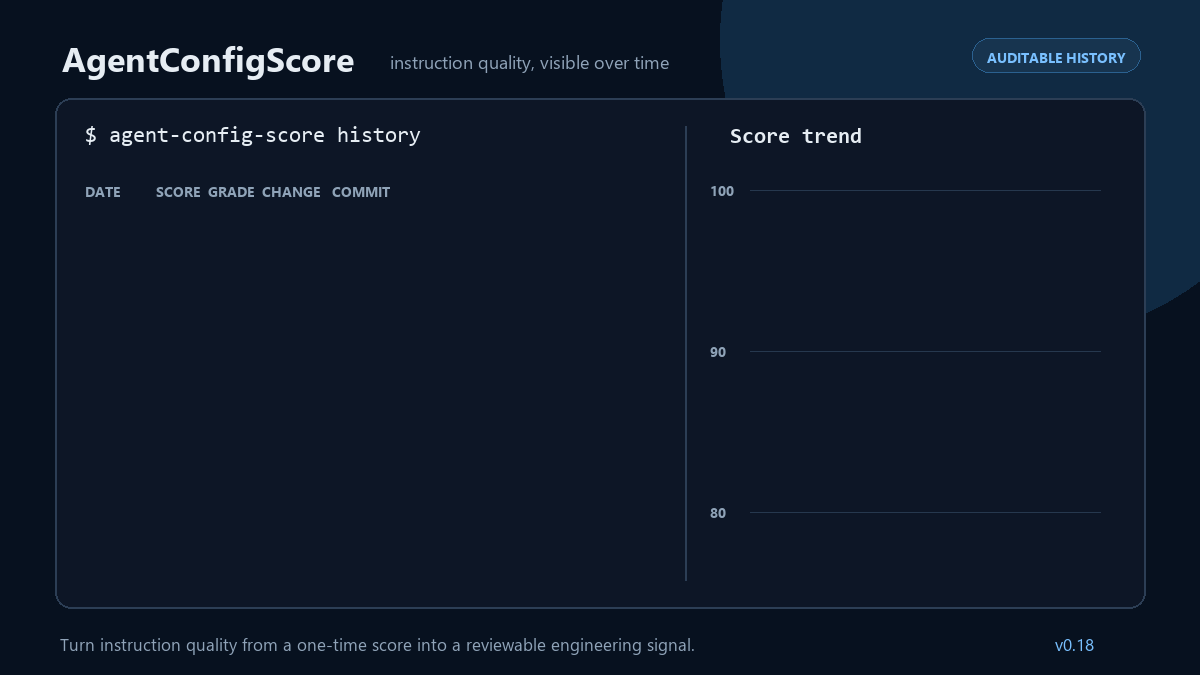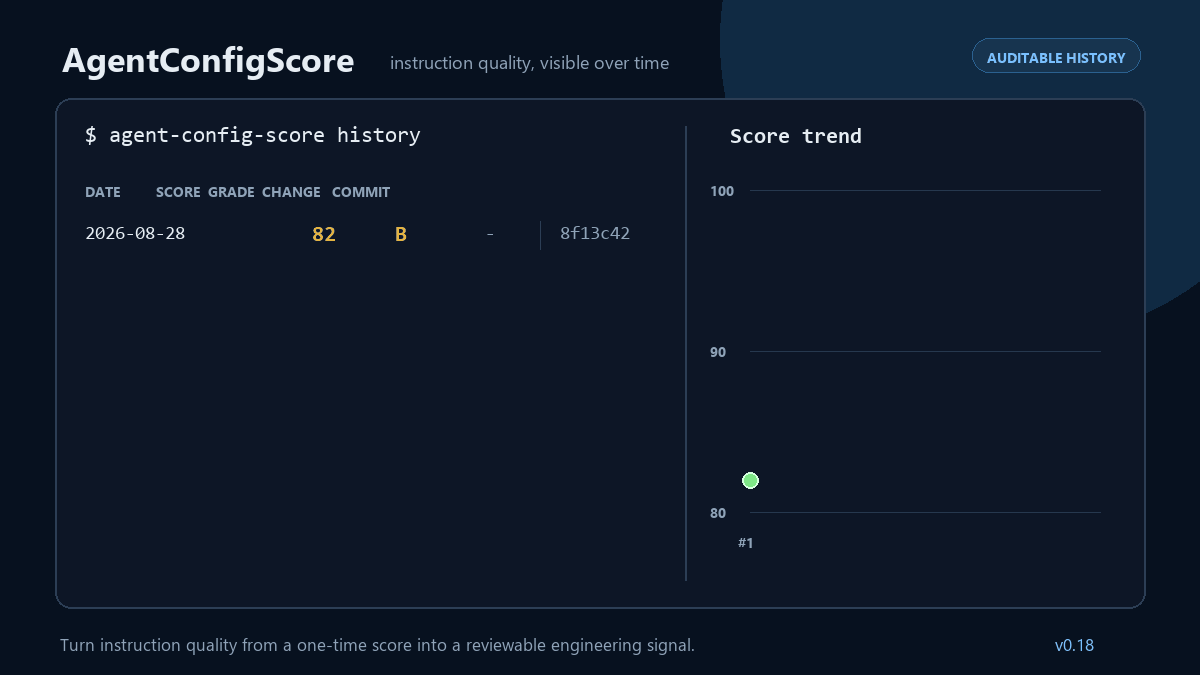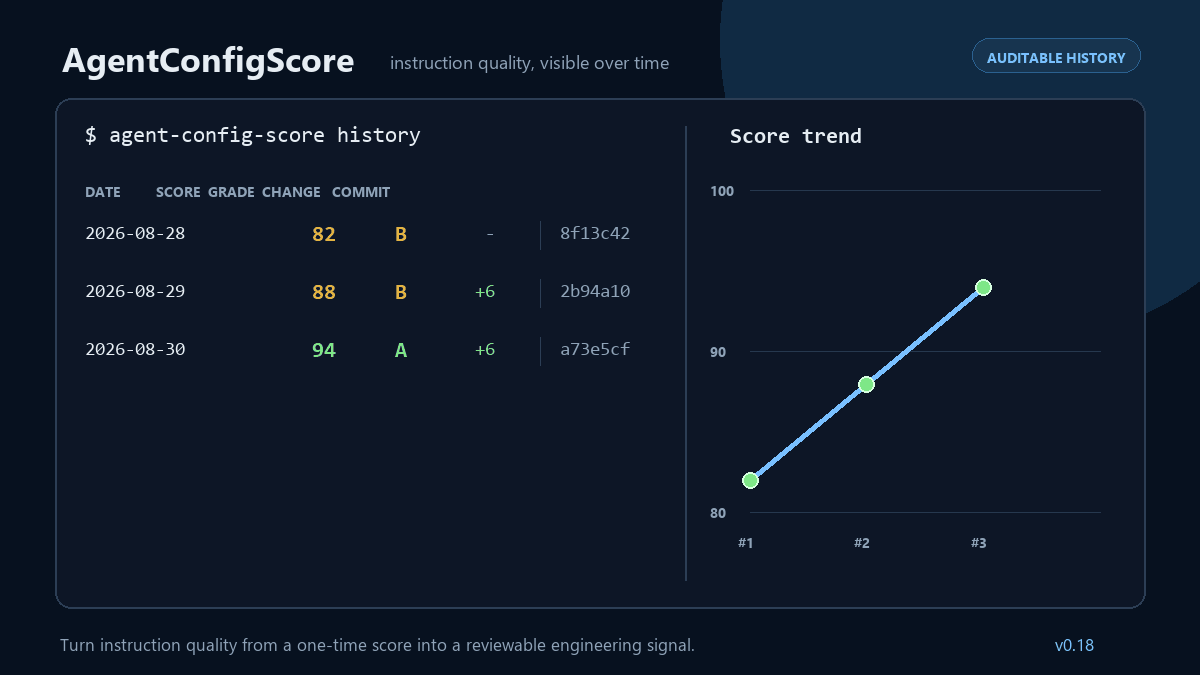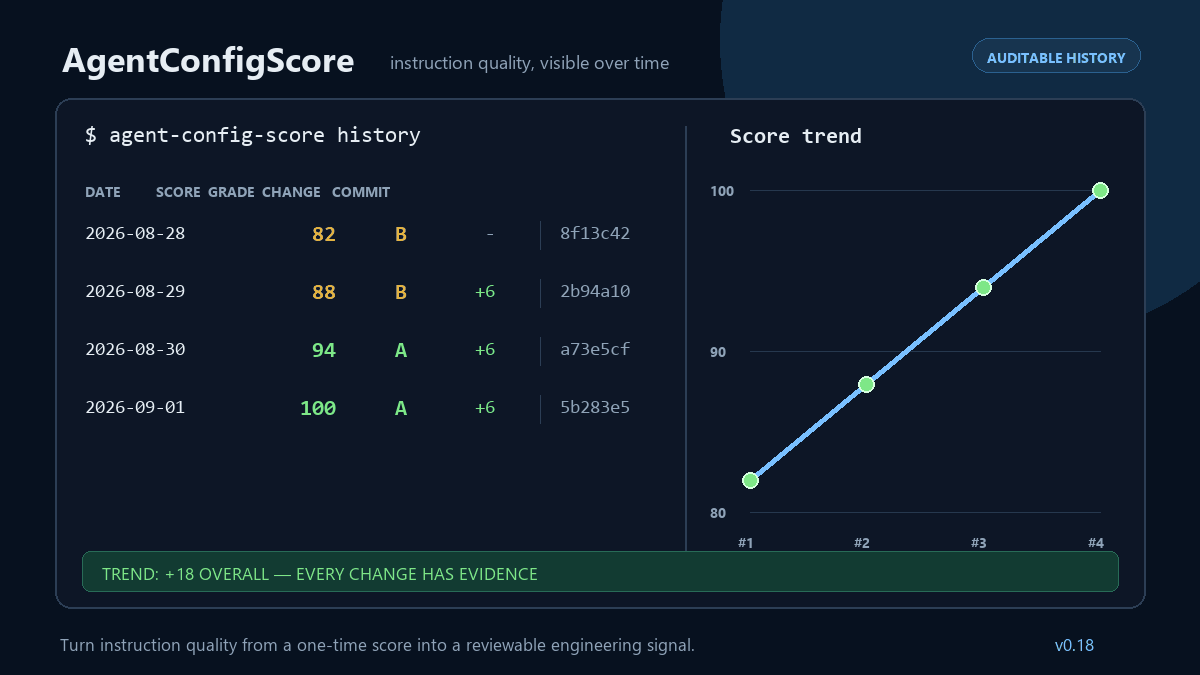
The visual tour explains each demo. Choose 简体中文 or 繁體中文 for the localized overview, guide and limitations; advanced references remain English.
python -m pip install -e .
python -m unittest discover -s tests -v
agent-config-score . --fail-under 90
Contributions and reproducible false-positive/regression cases are welcome. MIT licensed.